GeoLift vs. Meridian GeoX vs. Bell: Three Approaches to Geo Experimentation
Designing a high-power geo experiment is difficult, and there is no single methodology that is best in every setting. Here, we compare GeoLift, Meridian GeoX, and Bell to see how their different approaches to design, counterfactual estimation, and inference play out in practice.
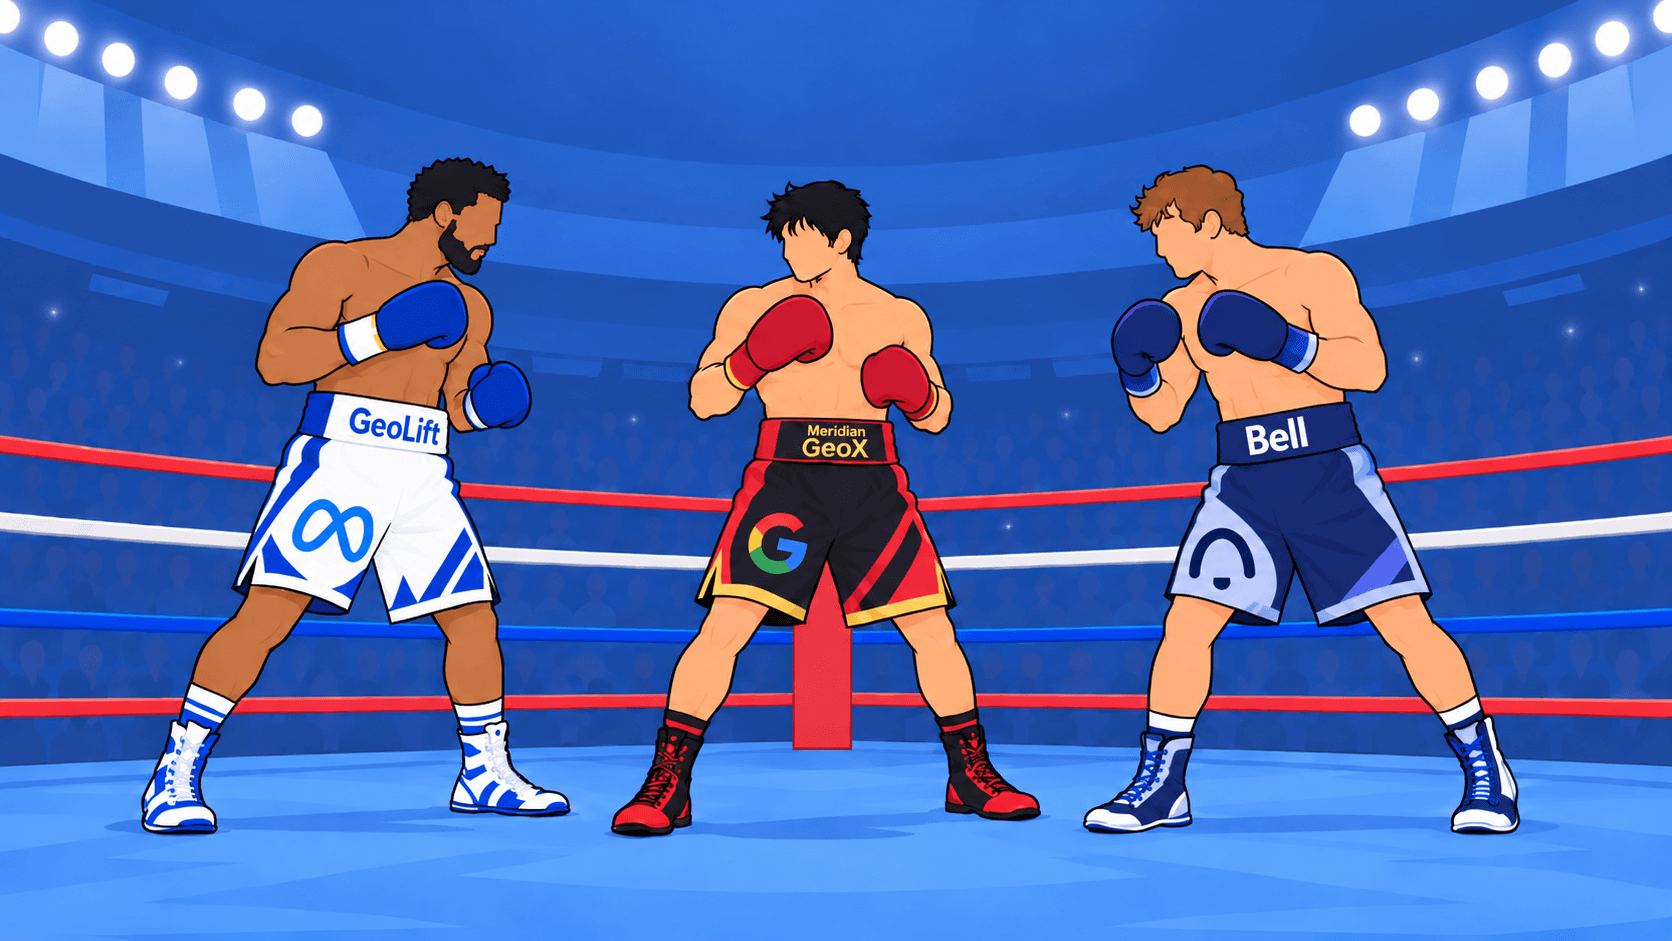
Designing a high-power geo experiment is difficult, and there is no single methodology that is best in every setting. Here, we compare GeoLift, Meridian GeoX, and Bell to see how their different approaches to design, counterfactual estimation, and inference play out in practice.
Geo experiments all start from the same basic idea.
A group of geographic markets receives a treatment, while the remaining markets are used to estimate what would have happened without it. The difference between what actually happened and that counterfactual is the estimated incremental effect.
But implementing this idea requires several methodological choices.
Which markets should be treated? How should the counterfactual be estimated? How should we decide whether a proposed design is sufficiently powerful? And, once the experiment is over, how should statistical significance and confidence intervals be calculated?
These choices are where the methodologies begin to diverge.
1. Finding a good allocation
The first problem is choosing which markets should receive treatment and which should remain as controls.
This is harder than it may initially appear. Even with a moderate number of markets, there can be trillions of possible treatment-control allocations. A practical methodology therefore needs a way to explore this space efficiently.
GeoLift searches for treatment groups whose markets correlate highly with one another, rather than with the control markets. The user specifies possible treatment-group sizes and effect sizes, and GeoLift compares candidate designs using simulated historical experiments. Using multiple historical lookback periods can make this evaluation more robust.
GeoX takes a more explicitly staged approach. It first uses historical characteristics of the geographies to create strata and then generates a large number of treatment-control candidates through stratified sampling. The candidates are subsequently evaluated on historical data that was not used to fit their counterfactual models.
At Bell, allocation search is an iterative optimization problem. We start from feasible treatment-control splits and progressively improve them according to how well the control markets predict the treatment group on held-out historical data. This makes out-of-sample counterfactual quality, rather than in-sample similarity, the main search target. Business constraints such as treatment volume and required market inclusion or exclusion are respected throughout, and the best candidates are then subjected to a more detailed statistical assessment before final selection.
2. Estimating the counterfactual
Once the allocation is chosen, the central statistical problem is estimating what would have happened to the treatment markets without treatment.
GeoLift uses Synthetic Control. The treatment series is approximated using a weighted combination of the control markets. GeoLift's implementation constrains those weights, including a sum-to-one restriction, which provides structure but can also become restrictive when treatment and control markets differ substantially in scale.
The current public implementation of GeoX instead uses Time-Based Regression (TBR). It aggregates treatment and control geographies into group-level time series and fits a linear relationship between them during the pre-experiment period.
Bell uses a regularized Synthetic Control. Control markets receive non-negative weights, while Elastic Net regularization is used to reduce the risk of fitting the historical period too aggressively. The amount of regularization is selected using rolling out-of-sample validation rather than in-sample fit alone.
GeoX deliberately uses a relatively simple relationship between the aggregated treatment and control groups. GeoLift and Bell instead allow individual control markets to contribute differently to the counterfactual.
3. Avoiding a design that only looks good historically
A geo experiment can appear excellent in historical data and still perform poorly once the real experiment begins.
This is essentially an overfitting problem.
The three frameworks address it differently.
GeoLift can evaluate candidate designs across multiple historical pseudo-experiment periods using its lookback-window feature. Using more such windows reduces the dependence of the design decision on one particular historical period.
GeoX makes the separation particularly explicit. Historical data are divided into Training, Validation, and Evaluation periods. Candidate designs are initially ranked according to their performance on the Validation period, while the final Evaluation period remains untouched until later design checks.
Bell uses rolling validation to select the Synthetic Control regularization strength, and out-of-bag sampling to evaluate prediction error and estimate uncertainty on unseen historical periods. It then performs a separate design-quality assessment, including a historical A/A test, checks for residual autocorrelation, and a check that the available history is sufficient relative to the complexity of the Synthetic Control and the planned experiment duration.
All three share the same principle: a good historical fit is not enough. What matters is whether the relationship continues to work on data that were not used to construct it.
4. Estimating the minimum detectable effect (MDE) and required budget
Before launching an experiment, we want to know whether it is capable of detecting an effect that is meaningful for the business.
This is where the Minimum Detectable Effect, or MDE, enters.
GeoLift estimates the performance and power of proposed designs through historical simulations on a small number of lookback windows (one by default). Those simulations are therefore central not only to selecting markets, but also to estimating the budget or effect size required for the experiment.
GeoX estimates uncertainty from the behavior of other candidate designs on its held-out Evaluation period and converts this into a percentage MDE using the desired significance level and statistical power.
Bell instead builds an empirical distribution of cumulative prediction errors from historical data. Historical test windows are evaluated out of sample, and the resampling method adapts to the time-series behavior of the residuals. This distribution is then used to derive the MDE.
5. Analyzing the experiment
The final difference appears once the campaign has actually run.
GeoLift uses conformal inference around its Synthetic Control estimates. It supports both IID and block-based inference, with the latter intended for cases where residuals exhibit temporal dependence. The choice is left to the user, and treating autocorrelated residuals as independent can lead to misleading inference.
GeoX estimates the incremental effect using the fitted TBR relationship and then performs inference using placebo experiments constructed from untreated geographies. The real and placebo effects are standardized by their own validation errors before p-values and confidence intervals are calculated from the empirical placebo distribution.
Bell also bases inference on the historical prediction errors of the Synthetic Control, but in contrast to GeoLift, uses out-of-bag prediction errors to avoid overfitting. The inference method (IID or block-based) is chosen automatically based on the pre-test observations.
Technical Comparison at a Glance
GeoLift | Meridian GeoX | Bell | |
|---|---|---|---|
Main counterfactual | Synthetic Control | Time-Based Regression | Regularized Synthetic Control |
Allocation approach | Historical simulation over candidate groups | Stratified candidate generation + out-of-sample ranking | Iterative optimization for out-of-sample counterfactual accuracy |
Protection against overfitting | Multiple historical lookback periods | Training / Validation / Evaluation split | Rolling validation + OOB evaluation + separate quality assessment |
MDE approach | Historical simulation on lookback windows | Held-out candidate-effect variability | Empirical distribution of out-of-sample prediction errors |
Inference | Conformal inference | Studentized geo placebos | Residual-based empirical inference |
Temporal dependence | IID or block, selected by user | Always assumes IID | IID or block chosen according to residual behavior |
6. A synthetic-data comparison
We've seen how the three methods differ in their approach to experiment design and statistical inference. But how do these differences translate into actual performance? To investigate, we tested all three methods on synthetic data, where the true treatment effect is known.
Generating the Data
To compare the three methods, we generated 1,000 synthetic datasets, each containing 30 geographic markets observed over 393 days: 365 days of historical data followed by a 28-day experiment.
The markets share common underlying trends but differ in their size and level of noise, creating realistic similarities and differences between their time series. In each dataset, 10 markets were randomly selected for treatment, with the remaining 20 serving as controls.
We then considered two scenarios: one with no treatment effect, to evaluate false positive rates, and another with a true 5% lift applied to the treatment markets during the experiment, to evaluate statistical power.
For each simulation, all three methods received the same data and treatment allocation, ensuring a direct comparison of their estimation and inference procedures rather than their market-selection strategies.
False Positive Rates
Before examining how well the methods detect real effects, we first ask a more fundamental question: How often do they report a statistically significant effect when no effect actually exists?
Using the 1,000 simulations without treatment effects, we measured the false positive rate of each method at a 10% significance level. Ideally, approximately 10% of experiments should produce a statistically significant result purely by chance.
The results reveal substantial differences between the methods:
Method | Significant by 90% CI | Significant by p-value | Discrepancies |
|---|---|---|---|
GeoX | 44.7% | 44.3% | 2.8% |
GeoLift | 3.0% | 10.6% | 7.7% |
Bell | 11.4% | 10.2% | 1.2% |
Expected | 10% | 10% | 0% |
GeoX produces false positives in roughly 44% of simulations, more than four times the expected rate. This suggests that its statistical inference is substantially overconfident under these simulated conditions.
Bell performs close to the expected level, with false positive rates of 10.2% by p-value and 11.4% by confidence interval. GeoLift also achieves a well-calibrated p-value false positive rate of 10.6%, but its confidence intervals tell a different story: only 3.0% exclude zero, suggesting considerably more conservative inference.
Ideally, a p-value below 0.10 and a 90% confidence interval excluding zero should lead to the same conclusion. However, the two disagree in 7.7% of GeoLift simulations, compared with 2.8% for GeoX and 1.2% for Bell.
Note: In 3.3% of GeoLift simulations, the confidence interval calculation failed, producing a zero-width interval. These cases were excluded from the confidence interval significance and discrepancy calculations, but retained in the p-value analysis.
Power Analysis
We next turn to the complementary question: When a real effect exists, how often does each method detect it? To answer this, we repeated the simulation exercise after applying a true 5% lift to the treatment markets during the 28-day experiment period.
The resulting detection rates measure the statistical power of each method. A more powerful method will identify the effect more often, provided its inference is also well calibrated.
The results again show clear differences:
Method | Significant by 90% CI | Significant by p-value | Discrepancies |
|---|---|---|---|
GeoX | 91.8% | 92.3% | 1.5% |
GeoLift | 47.3% | 61.9% | 16.4% |
Bell | 83.6% | 83.1% | 0.5% |
Target | 100% | 100% | 0% |
By p-value, GeoX detects the effect most often, with power of 92.3%, followed by Bell at 83.1%, and GeoLift at 61.9%. The same broad ranking appears when significance is assessed using 90% confidence intervals, although GeoLift’s power drops substantially to 47.3%.
As in the false positive analysis, Bell shows strong internal consistency: its p-values and confidence intervals almost always agree, with discrepancies in only 0.5% of simulations. GeoX is also fairly consistent, with discrepancies of 1.5%. GeoLift again stands out, with disagreements between the two significance criteria in 16.4% of simulations.
Note: In 1.8% of GeoLift simulations, the confidence interval calculation failed, producing a zero-width interval. These cases were excluded from the confidence interval significance and discrepancy calculations, but retained in the p-value analysis.
Comparing Confidence Interval Widths
Beyond statistical significance, we also examined how confident each method is in its estimated treatment effect. To do so, we compared the widths of the 90% confidence intervals for the estimated lift across the 1,000 simulations.
Narrower confidence intervals indicate greater precision in the estimate, but that precision is only trustworthy if the intervals accurately reflect the underlying uncertainty.
Method | Mean CI Width | 5th–95th Percentile Range |
|---|---|---|
GeoX | 3.45% | 1.18%–7.55% |
GeoLift | 11.80% | 2.85%–29.42% |
Bell | 5.99% | 2.49%–12.69% |
GeoX produces the narrowest confidence intervals, averaging 3.45%, followed by Bell at 5.99% and GeoLift at 11.80%. GeoLift's intervals also show substantially greater variability. However, narrower intervals do not necessarily indicate more reliable inference, as the false positive analysis demonstrates.
Simulation Summary
The simulations highlight an important trade-off between statistical power and reliable inference.
GeoX appears to be the most powerful method, detecting the true 5% effect in 92.3% of simulations. However, its false positive rate of 44.3%, far above the expected 10%, suggests that its narrow confidence intervals and high detection rate come at the cost of substantially overstating statistical confidence.
GeoLift maintains a well-calibrated false positive rate by p-value, but has considerably lower power (61.9%). Its confidence intervals are particularly conservative and frequently disagree with its p-values, raising concerns about the consistency of its inference.
Bell achieves the strongest balance in these simulations, combining high statistical power (83.1%) with a false positive rate close to the expected level (10.2%). Its confidence intervals and p-values also agree almost perfectly.
These findings are specific to the simulated data and should not be interpreted as a universal ranking of the three methods. Nevertheless, they illustrate a fundamental principle: the goal is not simply to detect as many effects as possible, but to detect real effects without frequently reporting ones that do not exist.
7. Which Methodology Should You Choose?
There is no single methodology that works best for every geo experiment. The right choice depends on the characteristics of the data and the trade-offs between simplicity, flexibility, and statistical reliability.
GeoLift may be a good choice when markets are roughly similar in size, since its Synthetic Control requires control weights to sum to one. It may also appeal to those who prefer a more conservative approach and are willing to sacrifice some statistical power to reduce false positives. Our simulations showed well-calibrated p-values, but relatively low power and particularly conservative confidence intervals.
Meridian GeoX may be a good choice when control markets behave similarly and their average closely tracks the treatment group. It may also be attractive when the treatment group is relatively small compared with the control group. GeoX favors sensitivity, detecting more real effects, but our simulations suggest that this comes at the cost of substantially more false positives. It may therefore appeal to those who prioritize detecting potential effects, even at the risk of more false alarms.
Bell may be preferable when markets differ considerably in size or behavior, since its more flexible Synthetic Control can accommodate these differences. It also includes safeguards against overfitting and unreliable inference. In our simulations, Bell achieved high power while maintaining false positive rates close to the expected level. Beyond its statistical approach, Bell is currently the only one of the three offering both a user interface and an MCP connector for Claude, allowing users to design, run, and analyze geo experiments without knowing R or Python.
Summary: what to ask of a geo methodology
Designing a geo experiment with enough statistical power is difficult. The choice of treatment markets, the quality of the counterfactual, the amount of historical data, and the way uncertainty is estimated can all materially affect whether a real effect can ultimately be detected.
GeoLift, Meridian GeoX, and Bell address these challenges in different ways. There is no single method that is necessarily best in every setting. The relative performance can depend on the structure of the geographic data, the amount of available history, the stability of relationships between markets, the experiment duration, and the size of the effect being measured.
Ultimately, a good geo-experiment methodology should not only find an allocation that looks promising historically. It should provide evidence that the counterfactual remains reliable out of sample and that the resulting experiment has a realistic chance of detecting the effect your business truly cares about.
Geo Testing at Bell Statistics
We plan, run and analyse geo experiments to measure what your marketing actually caused.
See how we work on geo testing →More on geo testing
All posts →
·8 min read
Geo Experimentation: How to Measure the Incremental Impact of Marketing
Marketing is a high-risk, high-reward investment for companies. On the one hand, effective marketing can have a significant impact on a product’s growth. On the other hand, marketing often involves massive budgets, making it critical to invest those resources where they can generate the greatest impact. As analysts, our goal is to determine whether, and to what extent, marketing investments actually drive incremental impact. How can we do that? In this blog, we introduce geo experiments, a powerful statistical approach for measuring the incremental impact of marketing campaigns. We’ll walk through what geo testing is, when it should be used, and why it can provide a more reliable measure of causal impact than common attribution models. If you’re looking for a robust way to measure the true impact of your marketing campaigns, this is where you should start.
Oryah Lancry Dayan
Lead Data Scientist
·3 min read
Geo Testing: Unlocking True Incrementality in Marketing and Product Experiments
Our “Geo Testing: Unlocking True Incrementality” webinar explored how teams can measure real-world impact when A/B testing isn’t possible - using geographic experiments and synthetic controls to reveal true incremental lift in marketing and product initiatives.
Allon Korem
Chief Executive Officer
·4 min read
Measuring the true effect of your ads with Geo Testing
Figuring out an ad's real effect is tricky. Clicks don't tell the whole story and attribution models fall short. The Solution: Geo Testing.
Amit Sasson
Causal Inference Expert